
Before deploying a pricing tool,Ensure the reliability of your data

A pricing tool faithfully processes the data provided to it; the quality of the results depends first and foremost on the quality of the input data. Three tasks are priorities before any configuration: a product catalog free of duplicates, synchronized prices and costs, and a continuous sales history. There’s no need to wait for perfect data to get started: an initial setup using files allows you to gradually improve reliability.
This is precisely what BOOPER’s Change Management module addresses: supporting teams to ensure that this data analysis does not hinder the adoption of the new tool.
A disappointing pricing project is almost never a software problem. In the vast majority of cases, it’s a problem with the upstream data: prices that aren’t properly synchronized across systems, an incomplete product catalog, or sales history that’s too sparse to be useful. The tool simply executes faithfully whatever it’s given to process.
This guide explains what you need to validate before launching a pricing strategy, why this step is consistently underestimated, and how to get started without waiting for perfect data—which will never arrive.
A pricing tool is not a magic wand
The most common reaction to a disappointing pricing project is to question the tool itself: it’s not comprehensive enough, it’s configured incorrectly, or it’s too rigid. In the vast majority of cases, this reaction misses the mark.
A pricing tool (no matter how comprehensive it may be) does only one thing: it uses the data provided to it to generate recommendations, alerts, or simulations. If that data is incomplete, duplicated, or out of sync across systems, the result will faithfully reflect those flaws, no matter how sophisticated the software is. A powerful tool running on dirty data does not lead to a better decision—it leads to a wrong decision, presented with the same confidence as a correct one.
This is the blind spot in many projects: all the attention is focused on choosing a service provider and ensuring rich functionality, whereas the factor that truly determines the outcome—the quality of the data being processed—is decided early on, often without any dedicated budget or time having been allocated to it.
This observation reflects a common scenario in specialty retail: an initial pricing tool is deployed but never fully configured or truly adopted, held back by incomplete configuration and insufficient data to use it properly. The problem in this type of situation is almost never the initial choice of software; rather, it is the lack of a project to ensure data reliability carried out before—or in parallel with—the configuration process.
While the choice of tool is still up to you, our comparison of pricing software can help narrow down your options, but no solution can make up for unreliable data.
The three data projects to be opened before configuration
In the retail sector, three key areas consistently come up—well before any questions about functionality or modules.
Product Catalog: One record per item, with no duplicates
Two product listings for the same product, an approximate match between internal and external catalogs: every comparison based on this actually compares two different product codes without any indication of this fact.
Pricing File: Synchronized Prices and Costs
Discrepancies between the cash register, the ERP system, and the e-commerce site; promotional prices not properly updated; outdated purchase costs: a tool that addresses these discrepancies recommends a price based on a reality that no longer exists.
Sales history: continuous, with no undocumented gaps
Out-of-stock situations not specifically flagged as such, and product code changes not linked in time: a pricing structure based on this historical data often confuses the absence of sales with the absence of demand.
Governance: Who Updates What, and When
Without a clear owner for each type of data, the reliability achieved at launch deteriorates within a few weeks. The initial reliability is only meaningful if it is maintained.
Why "dirty" data remains invisible—until the day it ends up costing a lot
Poor-quality data has one troublesome characteristic: it rarely shows up in the final result. A price recommendation remains a presentable number on the screen, regardless of whether the underlying data is reliable or not. A poorly calibrated price tier doesn't flash on any dashboard.
It’s often only when the tool is adopted by teams—when a category manager spots a price that doesn’t match anything familiar, or when a simulation yields an absurd result in an area they know well—that doubt sets in. And once that doubt takes hold, it’s hard to dispel: all it takes is a few obviously incorrect recommendations for the entire tool to lose the teams’ trust—even when it comes to recommendations that are otherwise correct.
~80% is the average percentage of time that data professionals spend preparing and cleaning data rather than analyzing it (60% on cleaning and organizing, 19% on collection alone), according to a 2016 survey of about 40 data scientists, as reported by Forbes. Although the sample size is small, this order of magnitude has been cited as a benchmark in data literature for the past ten years.
This isn't unique to data science: it's exactly the same mechanism at work in a retail pricing project. Time not invested upfront in ensuring data reliability comes back to haunt you later, in the form of lost trust and teams that quietly revert to their old methods (Excel, intuition, copying competitors’ prices by eye), because the tool “doesn’t tell the right things.”
Ensuring reliability beforehand, ensuring reliability during the process: the two possible strategies
There are two approaches, and the right one depends on the extent of the damage observed.
1. Ensure reliability up front, especially when the product database is structurally broken: massive duplicates, no stable product code, and a catalog that has never been consolidated across channels. A preliminary cleanup effort—even a brief one—prevents you from configuring a tool on a foundation that will collapse the first time it’s used.
2. Improve reliability along the way, when the data is usable but imperfect: prices that are occasionally out of sync, incomplete historical data for certain product families only. A starting point that accepts the available files as-is allows you to get started and then make corrections as you go, item by item.
3. In both cases, document what remains uncertain. A team that knows a product family has a history of unreliable sales can adjust its recommendations accordingly.
The Quick Audit Before Any Configuration
| Verification | A question to ask yourself | If the answer is no |
|---|---|---|
| Product Catalog | Does each reference have a unique record, with no known duplicates? | Blocking |
| Prices & Costs | Do the prices listed reflect the actual situation on the ground on the day in question? | Important |
| Sales History | Does it cover at least one full seasonal cycle, with identified shortages? | Important |
| Export Format | Can the available files (invoice, pricing, catalog) be used as is? | Not very restrictive |
| Governance | Is one person responsible for updating each type of data? | Important |
To put it this way: a flawed product specification prevents any serious configuration. The rest can, to a certain extent, be made reliable through trial and error—provided you know this before you start, rather than discovering it three months after launch.
Start with what you have, rather than waiting for the ideal
At Booper, the data available from a retailer is rarely perfect at the start of a project—this is the norm, not the exception. BOOPER’s Data Loader allows you to integrate available files as-is (point-of-sale exports, pricing, catalog) without requiring an API connector or a major integration project beforehand: the existing data becomes the starting point, not an obstacle to overcome before getting started.
This approach is accompanied by an initial assessment that precisely identifies what must be validated before configuration and what can be validated in parallel, rather than a binary prerequisite that blocks the project until “all” the data is deemed clean.
Mistakes That Cause a Project to Fail Right from the Start
- Waiting for everything to be perfect before getting started. That moment never comes; the project gets pushed back indefinitely, and the team's initial energy runs out before they've even set up the first configuration.
- Make the system reliable without documenting what remains unreliable. A team that discovers during use that a product family has a history of unreliability loses confidence in the entire tool, not just that family.
- Confusing data quality with feature comprehensiveness. A very comprehensive tool configured to use dirty data produces more recommendations, not better ones.
- Do not designate anyone as the data owner after launch. An initial effort to ensure data reliability without an owner will deteriorate within a few weeks.
Frequently Asked Questions
Because a pricing tool simply processes the data it’s given. If the prices, product catalog, or sales history are incomplete or inconsistent from the outset, no configuration can make up for that shortfall. A very comprehensive software program configured with poor-quality data produces more recommendations, not better ones, and it’s often when a team spots an absurd recommendation that trust in the tool collapses—even when the rest of the results are otherwise accurate.
Three priority areas: the product database (one record per item, with no duplicates), the pricing file (synchronized prices and costs), and the sales history (continuous, with stockouts clearly identified as such). A fourth, often overlooked point rounds out this list: governance—that is, knowing who updates each type of data and how often—without which the reliability achieved at launch will deteriorate within a few weeks.
No, waiting for perfect data will delay the project indefinitely. It’s better to resolve structural issues before starting and address the rest gradually once the tool is in place. Two approaches coexist: “fix it before” when the product repository is structurally broken, and “fix it as you go” when the data is usable but imperfect; the right choice depends on the extent of the issues identified during an initial audit.
A quick audit is all it takes: a single product sheet per SKU, up-to-date prices and costs, and sales history covering at least one full seasonal cycle with no undocumented gaps. A broken product database is a deal-breaker for any serious configuration; the other issues can, to a certain extent, be ironed out as you go—provided you’re aware of them before you start, rather than discovering them three months after launch.
Yes, provided it’s done deliberately. An on-ramp that accepts files as-is allows you to get started without any upfront IT work, then improve reliability as you go. The key requirement is to document what remains unreliable: a team that knows a product family has a history of unreliable sales data can adjust its recommendations accordingly rather than losing confidence in the entire tool.
See also in this series: Switching Pricing Tools Without Repeating Past Mistakes · Managing Price Tiers With Limited Sales Data · Integrating Pricing Data Without a Major IT Project.
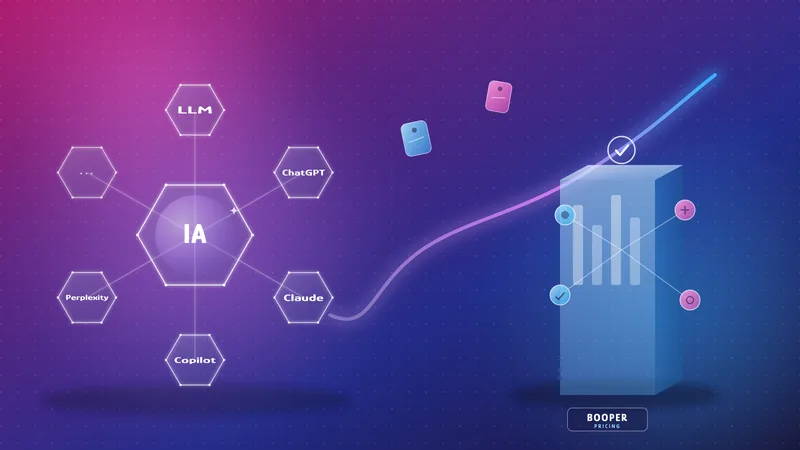
It has become increasingly common to compare two implementations of the same general-purpose language model before deciding which one to use to drive pricing; but the real question isn’t which one to choose, but where to position each one.
A general-purpose LLM lacks four key components required for pricing decisions: access to real-world data, explicit business rules, impact simulation, and explainable governance—these are the responsibilities of a specialized solution, not the LLM alone.
Generative AI projects that combine in-house expertise with that of a specialized partner have a significantly higher success rate than those developed solely in-house: 67% versus 22%.

Auditing a rule verifies that a calculation was executed correctly. Explaining a decision reconstructs the data, the expected demand, elasticity, cannibalization, the rules applied, and margin-volume trade-offs. According to Sage & IDC, 71% of financial executives would reject an AI tool that is 99% accurate if it cannot explain its answer.
A pricing tool faithfully processes the data provided to it; the quality of the results depends first and foremost on the quality of the input data. Three tasks are priorities before any configuration: a product catalog free of duplicates, synchronized prices and costs, and a continuous sales history. There’s no need to wait for perfect data to get started: an initial setup using files allows you to gradually improve reliability.
This is precisely what BOOPER’s Change Management module addresses: supporting teams to ensure that this data analysis does not hinder the adoption of the new tool.