
Price Monitoring and Web Scraping in Retail

Price monitoring is the goal—finding out at what price a product is sold by competitors; web scraping is the method that makes it possible to achieve this on a large scale, through an automated process rather than manual data collection.
The global web scraping market is estimated at $1.17 billion in 2026, driven notably by competitive intelligence and dynamic pricing (Mordor Intelligence).
“We’re already monitoring our competitors” is one of the most misleading statements in pricing. What it actually entails ranges from a spreadsheet updated manually once a month to an automated data collection pipeline that scrapes thousands of product pages every day. The difference between the two isn’t a matter of degree—it’s a matter of kind, and it determines whether your pricing decisions are based on a snapshot of the market or a moving picture.
A precise definition, not a buzzword
A price survey, strictly speaking, is the observation and recording of a product’s posted price at a given moment at one or more retailers. Nothing more. It’s a practice as old as commerce itself: a category manager who jots down the prices in a competitor’s aisle in a notebook is already conducting a price survey.
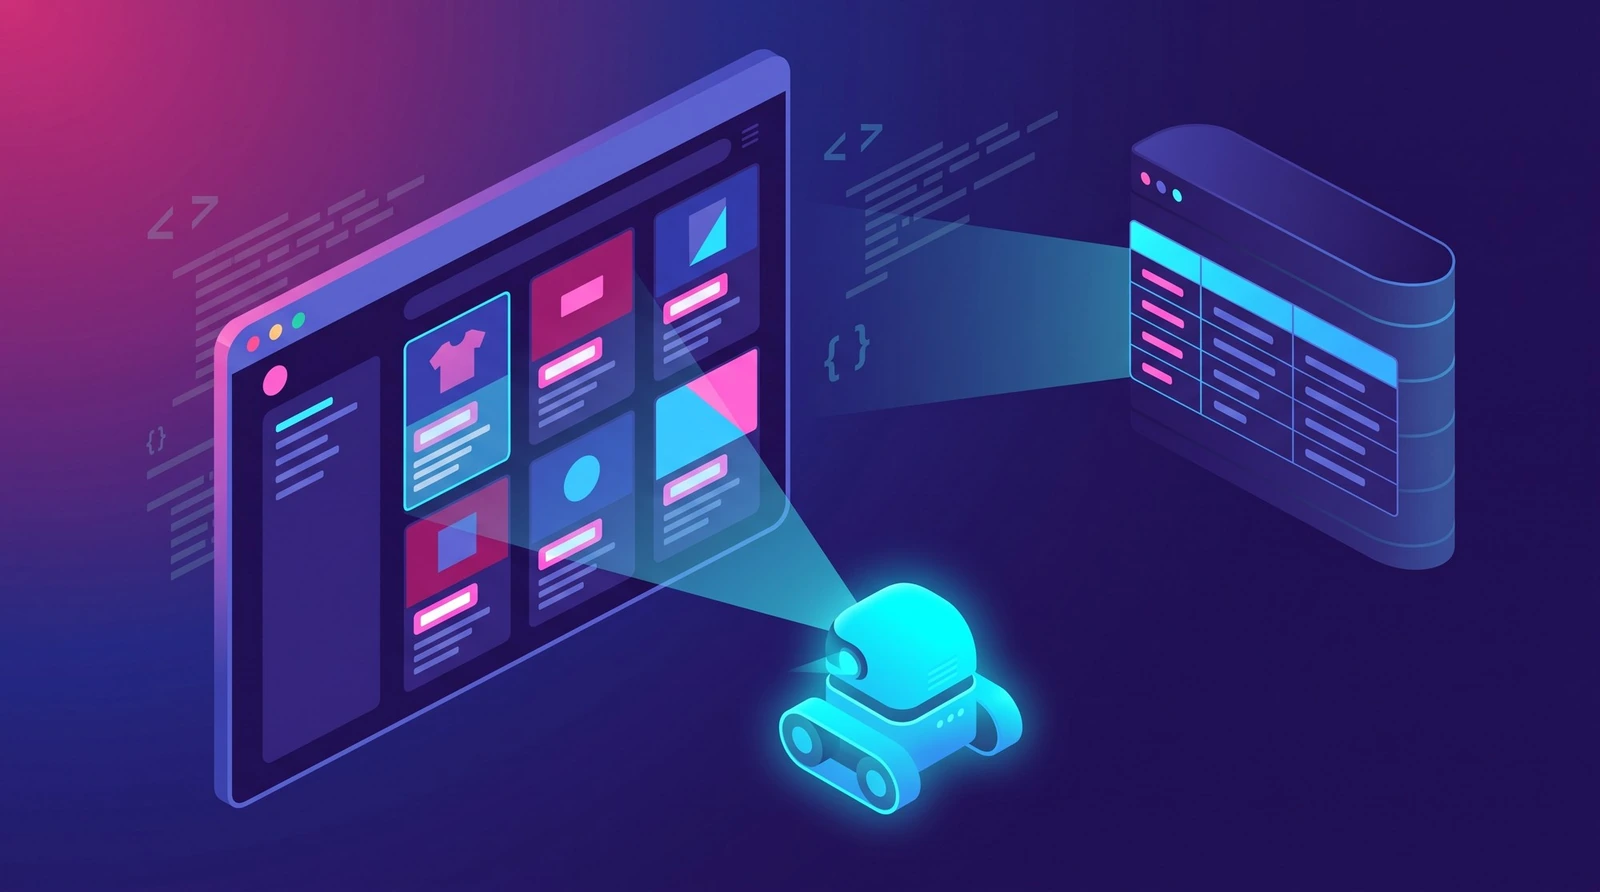
Web scraping is one of the methods used to generate this report—and the only one that can be scaled. Technically, it is an automated process that queries public web pages (product listings, category pages, search results, marketplaces) at scheduled intervals, extracts the displayed data (price, availability, promotions, product descriptions), and organizes it into a usable format—a database, not a screenshot.
The confusion stems from the fact that “price monitoring” can refer to three very different approaches in terms of reliability, cost, and timeliness: field surveys (a person visits locations or checks prices manually), web scraping (a bot collects data automatically), and retailer panels (a third party aggregates data from point-of-sale systems or panelists).
estimated size of the global web scraping market in 2026 across all sectors, driven by the adoption of competitive intelligence and dynamic pricing (Mordor Intelligence).
It is no longer a niche practice or a technical DIY project reserved for the most advanced e-retailers: it has become a foundational data infrastructure component, just like an ERP or PIM, with its own reliability requirements.
How automated price monitoring works technically
An automated price check is never just a single technology: it is a three-layer pipeline, and the quality of the final decision depends on its weakest layer, not its most impressive one.
Collection
Bots query product and category pages at scheduled frequencies across targeted retailers and marketplaces. Raw data does not yet hold decision-making value.
Product matching
Each collected price is matched against its corresponding internal product listing, even when naming conventions differ. This is the most critical and most frequently neglected step.
Reporting & alerts
Significant deviations are isolated and escalated to pricing teams rather than getting lost in a raw data stream. This is where data translates into decisions.
Many online price monitoring projects fail because they focus all their energy on the first layer (“we’ll scrape more competitors, more often”) while neglecting the next two.
Precisely for this reason, a senior category manager must evaluate a pricing intelligence solution based on the entire pipeline, not just the volume of data collected.
Four Ways to Create a Price Comparison: The Comparison
| Source | Freshness | Coverage | Cost | Main limitation |
|---|---|---|---|---|
| Manual field survey | Weekly to monthly | Low, limited sample | High | Does not scale beyond a few hundred SKUs. |
| Internal scraping (DIY) | Daily | Broad, but fragile | Moderate | Ongoing robot maintenance + custom matching to build |
| Specialized scraping provider | Real-time | Broad, pooled | Subscription | Third-party dependency for reliability and support |
| Retailer panels | Several weeks | Very broad in actual volume | High | Does not capture day-to-day price fluctuations |
How to read this: none of these four sources is universally superior. The right architecture typically combines multiple sources depending on the use case: scraping for daily pricing management, panels for validating long-term trends.
The five criteria that distinguish actionable data from a raw data feed
- The frequency adapted to the category, not a uniform frequency. A reference with high promotional rotation warrants daily, or even multi-daily, tracking.
- Actual coverage, not advertised coverage. A tool that "tracks 10 competitors" may fail to retrieve 20% of targeted pages without anyone knowing.
- The quality of product matching. Reconciling a scraped reference with its internal product page is the most critical and underinvested step in the process.
- The legal compliance of the setup. Scraping public data is regulated, not prohibited in principle.
- Decision-oriented reporting. What saves time is a system that isolates significant variances and alerts you to them.
Is web price scraping legal? What the current regulatory framework says
Legal Framework, CNIL, June 19, 2025
The CNIL acknowledges that web scraping of public data can rely on the legal basis of legitimate interest, subject to three cumulative conditions: a real and determined objective, the necessity of the processing to achieve it, and a favorable balance between the company's interest and the rights of the data subjects.
In practice, for standard B2B price monitoring—comparing publicly listed prices without personal data and without overloading the target server—the legal risk remains manageable, provided it is properly documented rather than ignored.
Four misconceptions that distort the analysis of price data
- "Web scraping is illegal." False as a general principle: the collection of public data is regulated, not prohibited.
- “The more competitors I have, the better my decisions.” This is false if product matching isn’t reliable; the method for prioritizing competitors will be the subject of a future article in this series, dedicated to developing a strategy for monitoring competitors’ prices.
- “A weekly report is enough.” This is not true for fast-moving categories—a topic we’ll explore in an upcoming article on the impact of up-to-date competitive data on pricing decisions.
- “Price monitoring is already a pricing strategy.” No: it’s an input, not a strategy.
Price tracking, the silent foundation of any pricing decision
A price survey is never an end in itself. It is the earliest input in any pricing decision, which means that any error made at this stage spreads—and is amplified—through every decision that depends on it.
At Booper
The GENIUS Link module uses NLP to automatically match your SKUs with those in competitors’ catalogs, providing a confidence score for each matched product. Downstream, GENIUS Monitoring centralizes alerts so that the collected data can be translated into decisions. It is this comprehensive process that now enables Coopérative U to manage several million prices per year across more than 1,700 stores while maintaining consistent pricing nationwide.
Discover how Booper structures this complete pipeline on our price tracking & web scraping page.
The checklist before trusting your price monitoring data
- Do you know the actual coverage rate of your setup, not just the number of "tracked" competitors?
- Is the collection frequency optimized category by category, or uniform by default?
- Is product matching measured with a confidence score, or taken for granted?
- Has the system been legally audited, or does it rely on the assumption that "everyone does it"?
FAQ
The questions we are most frequently asked before getting started.
See also: How to choose a tool for tracking competitors' prices and build a comprehensive price monitoring system.
A price survey, strictly speaking, is the observation and recording of a product’s listed price at a given moment at one or more retail locations. It is a practice as old as commerce itself: a category manager who jots down the prices in a competitor’s aisle in a notebook is already conducting a price survey.
In modern retail, this data can be collected in several ways: manually on-site, through online queries, via automated web scraping, or through retailer panels that aggregate point-of-sale data. Each method has its own data freshness, coverage, and cost.
What distinguishes a usable dataset from a mere stream of raw data comes down to five criteria: a frequency appropriate to the category, actual coverage (not just reported coverage), the quality of the product matching, the system’s legal compliance, and a presentation geared toward decision-making rather than a mere accumulation of numbers.
Price data collection is never an end in itself: it is the earliest input in any pricing decision, which means that any error made at this stage ripples out, amplified, into every decision that depends on it.
The goal of price monitoring is to determine the price at which a product is sold by competitors at a given moment. Web scraping is one method for achieving this—and the only one that truly scales beyond a few hundred SKUs.
Technically, web scraping is an automated process that queries public web pages (product listings, category pages, search results, marketplaces) at scheduled intervals, extracts the displayed data (price, availability, promotions), and organizes it into a usable database—it is not simply a screenshot.
The confusion stems from the fact that “price monitoring” can refer to three very different approaches in terms of reliability, cost, and timeliness: manual field data collection, automated web scraping, and retailer panels that aggregate third-party data.
The global web scraping market, across all sectors, is estimated to reach $1.17 billion by 2026, with adoption largely driven by competitive intelligence and dynamic pricing, according to Mordor Intelligence—a sign that this method is now a full-fledged component of data infrastructure, on par with ERP or PIM systems.
Yes, in principle: collecting public data is not prohibited. The rules depend on the nature of the data being collected, compliance with the terms of use of the relevant website, and the load placed on its server.
The CNIL clarified this framework on June 19, 2025: the collection of public data through web scraping may be based on the legal grounds oflegitimate interest, provided that three cumulative criteria are met: a genuine and specific purpose; the necessity of the processing to achieve that purpose; and a favorable balance between the company’s interests and the rights of the data subjects.
For standard B2B price monitoring—comparing publicly listed prices without personal data and without overloading the target server—the legal risk remains manageable, provided it is properly documented rather than ignored.
In fact, this is one of the five criteria that distinguish a usable dataset from a mere stream of raw data: a system’s legal compliance cannot be assumed—it must be audited.
It depends on the product category; there is no one-size-fits-all rule. A product with high promotional turnover warrants daily or even multiple daily inventory counts , while a product with a stable price can be checked on a weekly basis.
Applying a uniform frequency across an entire catalog wastes data collection capacity without improving relevance: this is one of the five criteria that distinguish a usable monitoring system from a mere data stream.
Furthermore, the four data collection methods do not all provide the same level of timeliness: manual field surveys are conducted weekly or monthly; internal data scraping allows for daily updates; a specialized service provider can provide near-real-time data; while retailer panels report data with a lag of several weeks.
A well-designed architecture typically combines several sources depending on the use case: web scraping for day-to-day pricing management, and a panel to validate long-term trends over time.
No, the two sources are complementary rather than competing. Retail panels (such as NielsenIQ or Kantar) aggregate actual sales data, but with a time lag of several weeks; this data is useful for validating underlying trends, not for guiding pricing decisions this week.
Web scraping, on the other hand, provides near-real-time data, product by product, making it the ideal tool for day-to-day pricing management—but limited to listed prices, without the depth of actual sales volume data that a panel provides.
A comparison of the four price-collection sources (field research, internal web scraping, specialized service providers, and panels) shows that none is universally superior: each has its own level of data freshness, coverage, and cost.
A good architecture generally combines both approaches: scraping for day-to-day responsiveness, and the distributor panel for validating long-term trends over a longer period.
Because collecting a price is only valuable if you can be certain that it corresponds to the exact same product reference as yours. In the three-layer pipeline of an automated price tracking system (collection, product matching, reporting, and alerts), product matching is the most critical—and most often overlooked— step.
Approximate matching produces discrepancies that appear real but are not, and that silently skew all repricing decisions based on them. Many price monitoring projects fail because they focus all their energy on data collection (“scraping more competitors, more often”) while neglecting this step.
That is why a monitoring system must be evaluated based on the entire pipeline, not just the volume of data collected: the quality of the final decision depends on the weakest link, not the most impressive one.
At Booper, this is precisely the function of the GENIUS Link module, which uses NLP to automatically match SKUs with a confidence score for each product—a comprehensive process that now enables Coopérative U to manage several million prices per year across more than 1,700 stores while ensuring consistent pricing nationwide.
An integrated solution combines competitor price collection, matching of equivalent products, and price recommendations into a single workflow. BOOPER thus links price collection, NLP-based matching with a confidence score (GENIUS Link), and price management, eliminating the need to re-enter data between tools.
Also in this series
- Scraping, field surveys, panelists: What are the differences?
- How to build a competitor price monitoring strategy
- The limitations of Excel for tracking competitor prices
Sources: Mordor Intelligence, Web Scraping Market Size & Share Report, 2026 · CNIL, The Legal Basis of Legitimate Interest: Data Collection via Web Scraping, June 19, 2025.
Seven criteria distinguish a competitor pricing monitoring tool that simply generates a table of price differences from one that actually drives decisions: coverage, recency, product matching, alerts, governance, integration, and compliance. The listed cost is only part of the total cost: manual reclassification, maintenance of in-house development, and the opportunity cost of a poorly informed decision often outweigh the subscription fee.
A comprehensive competitor pricing monitoring system is built on five inseparable components: data collection, matching, alerts, reporting, and governance; if even one of these components is missing, the system becomes ineffective. The retail sector revises its prices more frequently than any other (ranging from monthly to daily, depending on the category), which requires a system capable of keeping pace.
Many organizations receive a report on competitors’ price differences every morning, but few have a genuine strategy. The difference lies in three questions that must be asked before implementing the system: Why collect this data? What specifically should be tracked? And what decisions should be made once a price difference is identified?
Key point: Key value items (KVI) —the products whose prices customers remember—typically account for 15 to 25 percent of a category’s sales. Focusing monitoring efforts on this small core group is more cost-effective than trying to track everything with the same intensity.